 LotsBlog
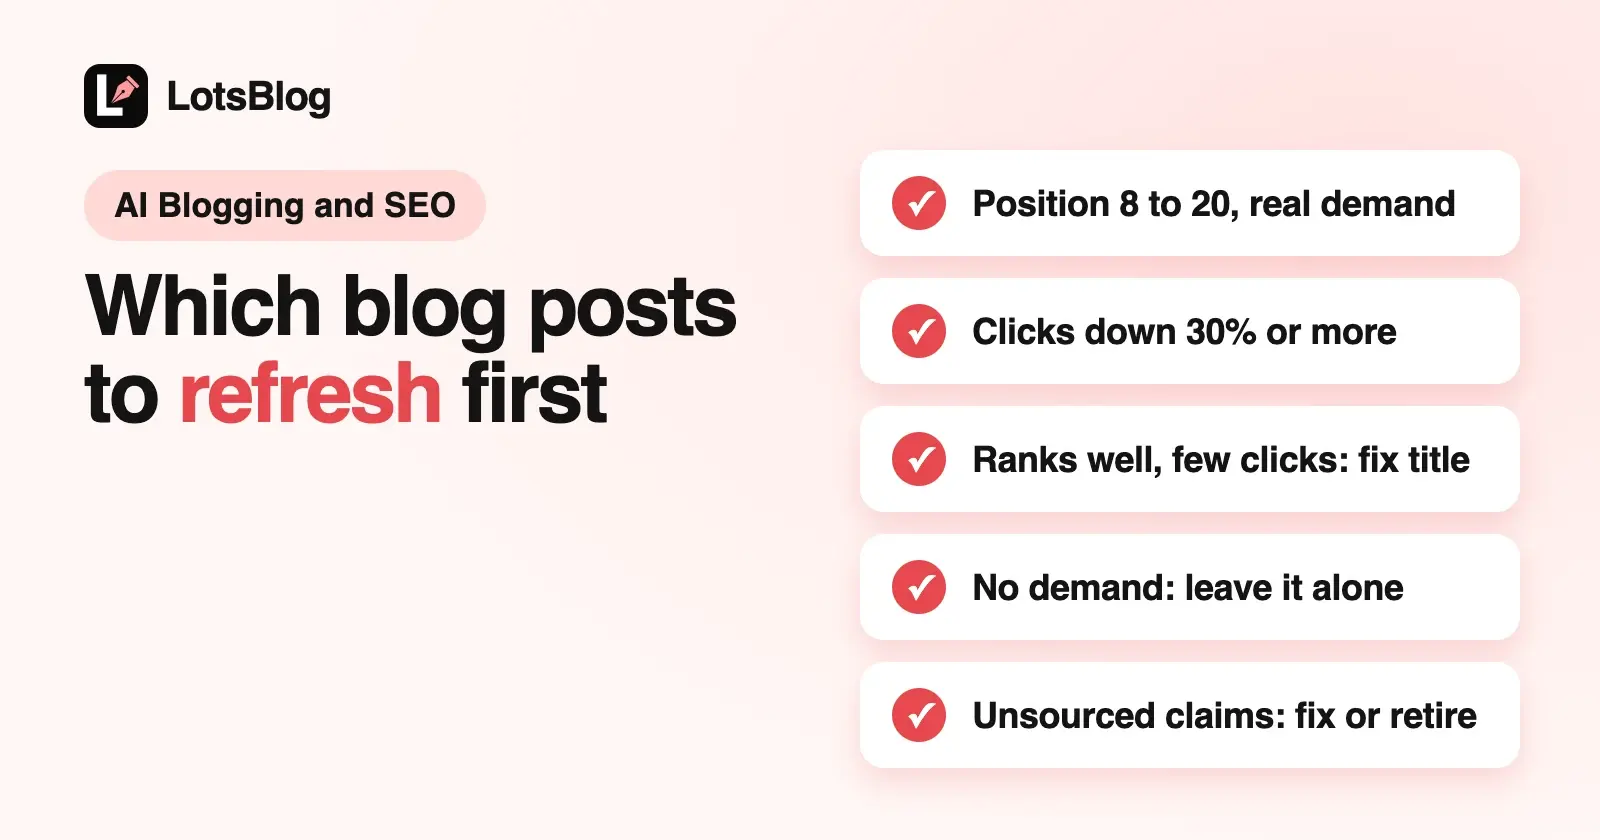
Refresh the posts that already have search demand and sit close to page one, then the ones losing clicks, and leave the rest alone. In Search Console that means comparing two equal date ranges for every page and sorting by average position, impressions and change in clicks. A short script below does that for you and labels each page, a step-by-step setup gets it connected to Search Console, and a decision table says what to do with each label. Nothing here needs a paid SEO tool.
The rules of thumb are mine, not Google's. The facts about how Google treats dates, sitemaps, 404s and the Search Console API come from Google's own documentation, which I opened on 8 October 2026 and link at the end.
Four signals decide what to do with a post
Search Console gives you, for each page, clicks, impressions, click-through rate and average position. Compare the last 28 days with the 28 days before them, and each post lands in one of these groups.
| Signal | What it looks like in Search Console | What to do |
|---|---|---|
| Striking distance | Average position 8 to 20, impressions at or above the median for your pages | Refresh first. The page already has demand and is close to page one. Rewrite the section that answers the query, current facts first |
| Decaying | Clicks down 30% or more against the previous period, from a base of at least 5 clicks | Refresh next. Check whether the loss is seasonal, then update facts that have changed |
| Weak title or snippet | Position 5 or better, impressions above the median, click-through rate under 2% | Rewrite the title and meta description, not the body |
| No real demand | Impressions come from queries that aren't about what the post covers, or almost none | Don't refresh. Leave it, merge it into a stronger post, or retire it |
| Claims you can't source | Any post, whatever its traffic | Fix every number against a primary source, or retire the post |
Position and click thresholds are rules of thumb. Change them to fit your own data, and keep one rule fixed: the query must match what the post is about. A page with a lot of impressions for a query it doesn't answer is a reason to write a better page, not to refresh this one.
What Google's documentation says that matters here
- The Performance report. By default it shows the past three months. In the table, a page's average position is the average for that URL, and in the chart it's the average position of your topmost result across the site. (Search Console Help, Performance report.)
- Sitemap dates. Google ignores
<priority>and<changefreq>, and uses<lastmod>only if it's consistently and verifiably accurate. It should reflect the last significant update: main content, structured data or links, not a copyright year. So don't bump the date without a real change. (Google Search Central, sitemaps, last updated 2026-07-08.) - Byline dates. Show a visible date and match it in structured data (
datePublishedanddateModified). The date must describe the publication or update of the page, not the events it covers, and Google doesn't guarantee a date is shown in results. (Google Search Central, publication dates, last updated 2025-12-10.) - 404 pages. For Google Search, the indexing pipeline removes a URL from the index if it was previously indexed and now returns 404, and the crawl rate for it gradually decreases. (Google Search Central, HTTP status codes, last updated 2026-02-04.) In practice the record can linger: on one of our own blogs, Search Console still showed URLs that now return 404 as "Submitted and indexed", because Google hadn't recrawled them yet.
- The Search Console API. The query endpoint returns up to 25,000 rows per request (the default is 1,000), dates are in Pacific time, and the per-site limit is 1,200 queries a minute. (Search Console API reference and usage limits, last updated 2025-08-28.)
Set up Search Console access for the script (about 15 minutes, once)
The script reads your Search Console data through the API, signed in as a "service account": a robot Google account with its own email address and a key file that proves it's that account. You create the account, download its key, save the key where the script looks for it, and then give the robot's email access to your property. Every step below is a click in a Google page or one line in a terminal.
Before you start, you need:
- The Google account that is an owner of the Search Console property. Google's help says only owners can add users. If your site isn't in Search Console yet, add and verify it first.
- Python 3 and
opensslin a terminal. macOS and Linux have both. On Windows, use WSL or Git Bash, because the script callsopenssl.
Step 1: create a Google Cloud project. Go to console.cloud.google.com and sign in with the same Google account. Click the project picker at the top, choose New project, name it something like blog-seo, and click Create. Make sure that project is selected for the next steps.
Step 2: turn on the Search Console API. In the left menu open APIs & Services, then Library. Search for Google Search Console API, open it and click Enable.
Step 3: create the service account. Open IAM & Admin, then Service Accounts, and click Create service account. Name it search-console-reader, click Create and continue, skip the optional role and access steps, and click Done. In the list you'll see its email address, which looks like search-console-reader@blog-seo-123456.iam.gserviceaccount.com. Copy it. You'll paste it into Search Console in step 6.
Step 4: download its key. Click the service account's email, open the Keys tab, click Add key, then Create new key, choose JSON and click Create. A .json file downloads to your Downloads folder. Google says you can't download it again, so don't delete it yet. If Create is blocked with a message about service account key creation being disabled, your organization has the iam.disableServiceAccountKeyCreation policy on, which Google enforces by default for organizations created on or after 3 May 2024. A Google Cloud organization policy admin has to exempt this project. A personal Google account without an organization normally doesn't hit this.
Step 5: put the key where the script looks. Open a terminal and run these three commands. The first makes the folder, the second moves and renames the file, and the third makes it readable only by you:
mkdir -p ~/.config
mv ~/Downloads/blog-seo-*.json ~/.config/gsc-key.json
chmod 600 ~/.config/gsc-key.json
If the second command says there's no such file, run ls ~/Downloads and use the real file name Google gave it: it starts with your project's ID. Check that it worked with ls -l ~/.config/gsc-key.json, which should show one file. To keep the key somewhere else, point the script at it instead:
export GSC_KEY=/full/path/to/your-key.json
The key is a password. Don't commit it to a repository, don't email it, and don't paste its contents into a chat. If it leaks, open the service account's Keys tab, delete that key and create a new one.
Step 6: give the service account access in Search Console. Open Search Console, choose your property, then Settings, Users and permissions, Add user. Paste the service account's email from step 3, set the permission to Full, and click Add. Do this for every property you want to read. The script asks Google only for read access, so it can't change anything in Search Console.
Step 7: save the script and test the connection. Save the code below as refresh_candidates.py. Then run:
python3 refresh_candidates.py sites
You should see a list of properties with the permission next to each, for example siteFullUser sc-domain:example.com. Copy the property exactly as it's printed: a domain property starts with sc-domain:, and a URL-prefix property is a full address with a trailing slash. If the list is empty, step 6 hasn't been done for that property.
Step 8: run it.
python3 refresh_candidates.py sc-domain:example.com
If something goes wrong, find your error here:
| What you see | What it means | Fix |
|---|---|---|
FileNotFoundError mentioning gsc-key.json | The script can't find the key | Run ls -l ~/.config/gsc-key.json; redo step 5, or set GSC_KEY to the file's full path |
No properties yet | The service account isn't a user on any property | Do step 6 and run the sites command again |
HTTP 403 and "User does not have sufficient permission for site" | The property string doesn't match, or this property hasn't added the service account | Copy the property exactly from the sites output, including sc-domain: or the trailing slash |
HTTP 403 and a message that the Search Console API has not been used in the project, or is disabled | The API isn't enabled in the project that owns the key | Do step 2 in the same project, wait a few minutes and run it again |
invalid_grant | The key was deleted, or your computer's clock is wrong | Set your clock to automatic, or create a new key in step 4 |
openssl: command not found | openssl isn't installed | On Windows, run it in WSL or Git Bash |
The script that labels every page
This reads the last 28 days and the 28 days before, labels each page, and prints them in priority order. It uses only Python's standard library and openssl, and a read-only Search Console scope.
#!/usr/bin/env python3
"""Rank blog pages for refresh using Search Console. Standard library and openssl only.

Usage: python3 refresh_candidates.py sites                      # list the properties the key can see
       python3 refresh_candidates.py <property> [days=28]       # rank pages for refresh
  <property> is the exact Search Console property, e.g. https://blog.example.com/ or sc-domain:example.com
Key: a service account JSON (added as a user on the property) at ~/.config/gsc-key.json, or set GSC_KEY
"""
import base64, json, os, subprocess, sys, tempfile, time, urllib.parse, urllib.request
from datetime import date, timedelta

KEY = os.path.expanduser(os.environ.get("GSC_KEY", "~/.config/gsc-key.json"))
b64 = lambda b: base64.urlsafe_b64encode(b).rstrip(b"=").decode()

def fetch(req):                                      # show Google's error message instead of a bare traceback
    try:
        return json.load(urllib.request.urlopen(req))
    except urllib.error.HTTPError as e:
        sys.exit(f"HTTP {e.code}: {e.read().decode()[:400]}")

def token():
    k, now = json.load(open(KEY)), int(time.time())
    head = b64(b'{"alg":"RS256","typ":"JWT"}')
    claim = b64(json.dumps({"iss": k["client_email"], "scope": "https://www.googleapis.com/auth/webmasters.readonly",
                            "aud": k["token_uri"], "iat": now, "exp": now + 3000}).encode())
    with tempfile.NamedTemporaryFile("w", delete=False) as f:
        os.chmod(f.name, 0o600); f.write(k["private_key"])
    try:
        sig = subprocess.run(["openssl", "dgst", "-sha256", "-sign", f.name], input=f"{head}.{claim}".encode(),
                             capture_output=True, check=True).stdout
    finally:
        os.unlink(f.name)
    body = urllib.parse.urlencode({"grant_type": "urn:ietf:params:oauth:grant-type:jwt-bearer",
                                   "assertion": f"{head}.{claim}.{b64(sig)}"}).encode()
    return fetch(urllib.request.Request(k["token_uri"], body))["access_token"]

def pages(site, tok, start, end):
    url = f"https://www.googleapis.com/webmasters/v3/sites/{urllib.parse.quote(site, safe='')}/searchAnalytics/query"
    req = urllib.request.Request(url, json.dumps({"startDate": str(start), "endDate": str(end), "dimensions": ["page"],
                                 "rowLimit": 25000}).encode(), {"Authorization": f"Bearer {tok}", "Content-Type": "application/json"})
    return {r["keys"][0]: r for r in fetch(req).get("rows", [])}

if sys.argv[1] == "sites":
    req = urllib.request.Request("https://www.googleapis.com/webmasters/v3/sites", headers={"Authorization": f"Bearer {token()}"})
    print("\n".join(f"{s['permissionLevel']}  {s['siteUrl']}" for s in fetch(req).get("siteEntry", [])) or "No properties yet: add the service account as a user in Search Console")
    sys.exit(0)
site, days = sys.argv[1], int(sys.argv[2]) if len(sys.argv) > 2 else 28
end = date.today() - timedelta(days=3)           # Search Console data lags by a couple of days
cur_start, prev_end = end - timedelta(days=days - 1), end - timedelta(days=days)
tok = token()
now, before = pages(site, tok, cur_start, end), pages(site, tok, prev_end - timedelta(days=days - 1), prev_end)
imps = sorted(r["impressions"] for r in now.values()) or [0]
median = imps[len(imps) // 2]

rows = []
for url, r in now.items():
    prev = before.get(url, {"clicks": 0, "impressions": 0})
    label = "leave"
    if 8 <= r["position"] <= 20 and r["impressions"] >= median:
        label = "striking distance"                          # close to page one, with real demand
    if prev["clicks"] >= 5 and r["clicks"] <= 0.7 * prev["clicks"]:
        label = "decaying"                                   # lost 30% or more of its clicks
    if r["position"] <= 5 and r["impressions"] >= median and r["ctr"] < 0.02:
        label = "weak title or snippet"                      # ranks well, few clicks
    rows.append((label, url, r["impressions"], r["clicks"], r["position"], r["clicks"] - prev["clicks"]))

order = {"decaying": 0, "weak title or snippet": 1, "striking distance": 2, "leave": 3}
print(f"{cur_start}..{end} vs the {days} days before. Median impressions per page: {median}\n")
for label, url, i, c, p, d in sorted(rows, key=lambda x: (order[x[0]], -x[2])):
    print(f"{label:<22} {i:>6} impr {c:>4} clicks ({d:+d}) pos {p:5.1f}  {url}")
Each output line reads: the label, impressions, clicks with the change against the previous period, average position and the URL. I ran this against real Search Console properties before putting it here.
Then look at the queries behind your top candidates. In Search Console, open Performance, filter by the page, and read the Queries tab. The query you're closest to winning tells you which section of the post to rewrite.
Check the claims before you touch the traffic
A post can have every right signal and still not be worth keeping if its numbers can't be traced. Before refreshing, read the post and list every statistic, price and "according to" line. For each one, open the source and confirm the number and its date. If you can't find it, cut the sentence. Putting a fresh date on a post that still has unsourced figures makes it look newer and doesn't make it more accurate.
Refresh through your agent, keeping the URL
If your blog runs on LotsBlog, your agent can do the refresh through the MCP server without losing the URL:
- Give it the output of the script and the post's slug.
- It reads the post with
get_blog_post, checks each claim against its source, and rewrites the post. - It saves the change to the same post with
update_blog_post. Don't create a new post: slugs must be unique in a blog, so a second post can't take the old URL. - You read the preview. Nothing publishes until you say so, then
publish_postmakes it live at the same address.
A post you unpublished earlier is a draft, and its URL returns 404 until you publish it again. To bring an old URL back, rewrite the draft and publish it. Don't republish it unchanged.
A prompt that works:
Here is my refresh script output. Take the top "striking distance" page. Read the post, list every claim with its source, check each source today, and rewrite the sections that answer the top query for that page. Cut any claim you can't verify. Save to the same post, keep the slug, and give me the preview link. Don't publish.
What not to refresh
- Pages with no demand. If nobody sees them and no query matches what they cover, a rewrite won't create demand.
- Pages that promise something you don't do. Retire them. A 404 is better than a false promise.
- Pages where the only traffic is an unrelated query. Write a page for that query if it matters to you, or ignore it.
- Everything at once. Refresh in batches of a few posts, then check Search Console after Google has recrawled them before you choose the next batch.
Run your blog from your agent
Give your agent this and let it set itself up:
Read https://lots.blog/skill.md and help me connect LotsBlog for you.
LotsBlog costs $9 per blog, or plans from $24 for 3 blogs, with unlimited posts and page views. New accounts get 10,000 free credits, valid 90 days, no card. See pricing. If you use an agent to write, read what Google's own guidance says about AI-written posts first.
Common questions
How do I know which blog posts to refresh first?
Compare the last 28 days with the 28 days before in Search Console, per page. Refresh first the pages with average position 8 to 20 and above-median impressions, then the ones that lost 30% or more of their clicks. Skip pages with no demand for what they cover.
Do I need to change a post's date when I refresh it?
Only if the page has changed in a way that matters. Google's guidance says dates must describe the page's publication or update, and that <lastmod> in a sitemap should reflect a significant update. Changing a date without a real update works against that.
What happens if I delete or unpublish an old post?
The URL returns 404, and Google's documentation says that for a URL it previously indexed, the indexing pipeline removes it from the index, with the crawl rate gradually decreasing. Search Console can keep showing the URL as indexed until it recrawls it.
Can I do this without the script or the API?
Yes. In Search Console open Performance, choose Pages, set the date range to the last 28 days with a comparison against the previous 28 days, turn on impressions, clicks and average position, and sort by impressions. The script does the same comparison for every page at once and labels the result.
Is it safe to give a service account access to Search Console?
The script requests a read-only scope, so it can read performance data and can't change anything. Keep the key file private, give it only to the property you want to read, and delete the key in Google Cloud if it leaks.
How often should I refresh posts?
Google doesn't publish an interval. Run the script monthly and refresh the top few candidates, or whenever a price, limit or policy you wrote about changes.
Can an AI agent refresh posts for me?
Yes. Give it the script output and the post, and ask it to verify every claim and save to the same post as a draft. You approve the result before it's published.
Details checked on 8 October 2026 from Search Console Help: Performance report, Google Search Central: build and submit a sitemap, publication dates, HTTP status codes, the Search Analytics query reference and the Search Console API usage limits. Google can change its guidance; check its pages for the latest.