 LotsBlog
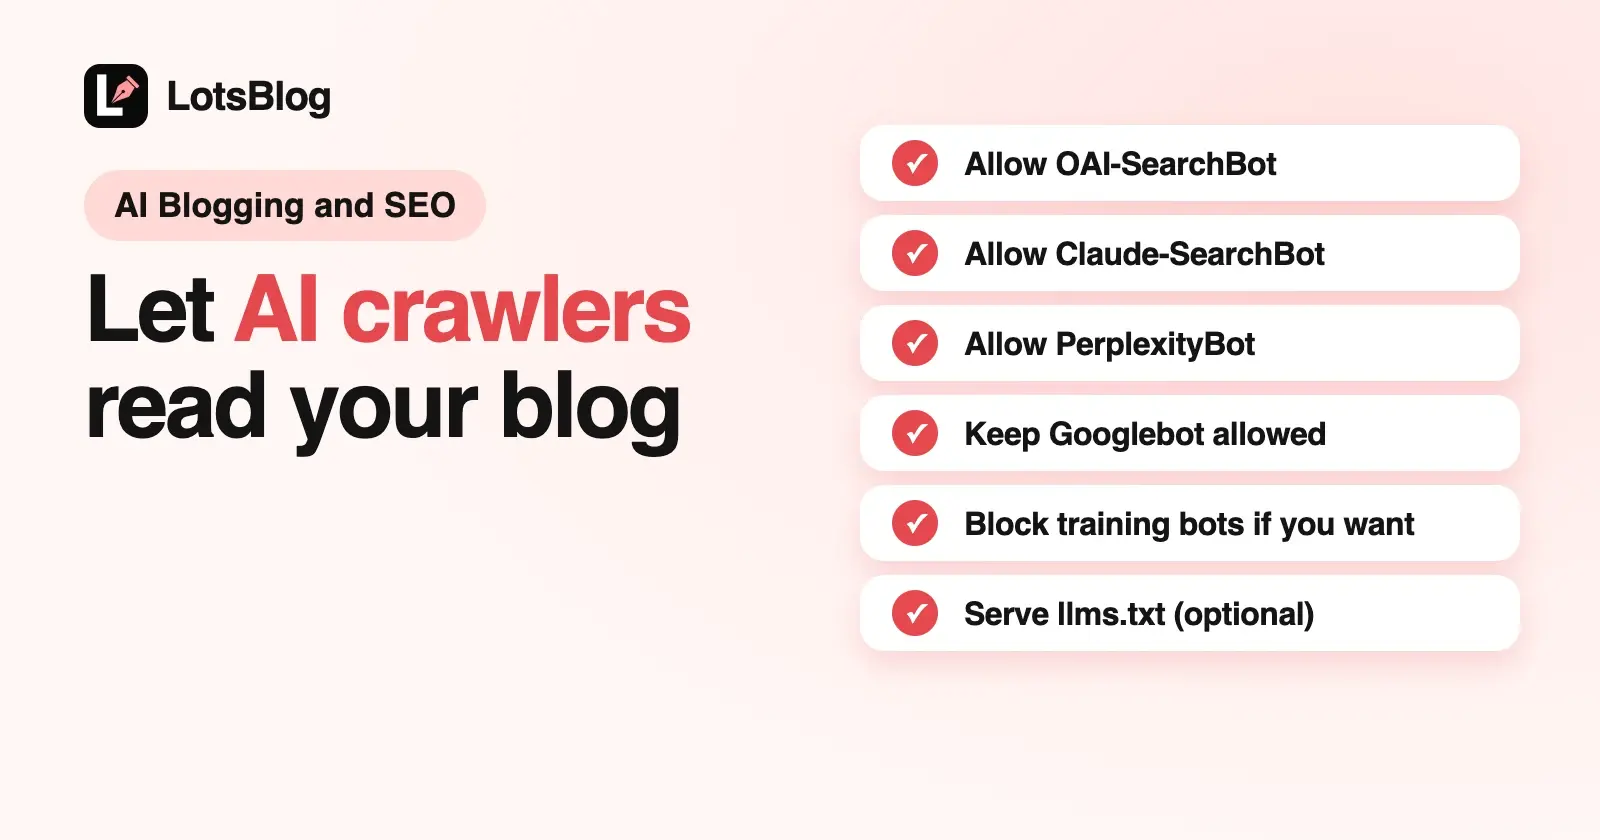
To let AI tools read and cite your blog, allow their search crawlers in robots.txt: OAI-SearchBot (ChatGPT search), Claude-SearchBot (Claude), PerplexityBot (Perplexity) and Googlebot (Google Search, including AI Overviews). Training is a separate switch. Disallow GPTBot, ClaudeBot, Google-Extended, Applebot-Extended and CCBot if you don't want your posts used to train models, and you stay visible in AI search. Each vendor documents training and search as separate controls, so blocking training doesn't remove you from their answers.
There is a third kind of visitor too: the fetch a person triggers by asking a chatbot about your page. OpenAI says robots.txt rules may not apply to ChatGPT-User, and Perplexity says Perplexity-User generally ignores robots.txt. Anthropic says all three of its bots honor robots.txt.
llms.txt is the other file people ask about. It doesn't allow or block anything: it's an optional Markdown map of your site for AI agents. Google says you don't need it to appear in AI Overviews or AI Mode, and Chrome's Lighthouse checks for it but treats it as optional.
I read each vendor's own crawler page on 11 October 2026. Below is what each one says, two robots.txt files you can paste, what llms.txt does and doesn't do, and what our own blog serves.
Every AI crawler token, from each vendor's docs
| Vendor | robots.txt token | What it's for (per the vendor) | Follows robots.txt? |
|---|---|---|---|
| OpenAI | GPTBot | Crawls content that may be used to train its foundation models | Yes |
| OpenAI | OAI-SearchBot | Surfaces sites in ChatGPT search results | Yes |
| OpenAI | ChatGPT-User | Visits a page when a user asks ChatGPT or a Custom GPT; not automatic crawling, not used for Search | May not apply, says OpenAI |
| Anthropic | ClaudeBot | Collects web content that could contribute to model training | Yes |
| Anthropic | Claude-SearchBot | Indexes content to improve Claude's search results | Yes |
| Anthropic | Claude-User | Fetches pages when a Claude user asks a question | Yes |
| Perplexity | PerplexityBot | Surfaces and links sites in Perplexity search results; not used for training foundation models | Yes |
| Perplexity | Perplexity-User | Visits a page to answer a user's question; not used for crawling or training | Generally ignores it, says Perplexity |
Googlebot | Google Search, including all Search features (AI Overviews and AI Mode follow its rules), Discover, Images, News | Yes | |
Google-Extended | Not a crawler. A control token for training future Gemini models and for grounding in Gemini Apps and Vertex AI | Yes (it is a robots.txt token only) | |
| Apple | Applebot-Extended | Not a crawler. Decides whether Applebot's data may train Apple's foundation models | Yes (robots.txt token only) |
| Common Crawl | CCBot | Crawls for Common Crawl's open repository of web data | Yes |
Sources and dates are at the end of this post.
What each vendor says, and what it means for a blog
OpenAI: GPTBot, OAI-SearchBot, ChatGPT-User
OpenAI's bots page says each setting is independent: you can allow OAI-SearchBot to appear in search results and disallow GPTBot so your content isn't used to train its foundation models. A site that opts out of OAI-SearchBot won't be shown in ChatGPT search answers, though it can still appear as a navigational link. OpenAI says it can take about 24 hours after a robots.txt change for search to adjust.
ChatGPT-User is the fetch that happens when someone asks ChatGPT about a page. OpenAI says it isn't used for automatic crawling or to decide what appears in Search, and that because a user starts it, robots.txt rules may not apply. OpenAI also lists OAI-AdsBot, which only visits pages submitted as ChatGPT ads.
Anthropic: ClaudeBot, Claude-SearchBot, Claude-User
Anthropic's help page (dated 7 April 2026) lists three bots. Blocking ClaudeBot signals that your future materials should be excluded from training. Blocking Claude-SearchBot stops Anthropic from indexing your content for search, which the page says may reduce your visibility in Claude's search results. Blocking Claude-User stops Claude from fetching your pages when a user asks, with the same visibility warning.
Two details matter for blogs. Anthropic says its bots honor robots.txt, including the non-standard Crawl-delay. And it asks you to add the rule to every subdomain you want to opt out, so a blog on blog.yourdomain.com needs its own robots.txt; the one on your main site doesn't cover it. Anthropic also warns that blocking its IP addresses instead may not work reliably, because then it can't read your robots.txt.
Perplexity: PerplexityBot, Perplexity-User
Perplexity's crawler page says PerplexityBot surfaces and links websites in its search results and isn't used to crawl content for AI foundation models. It recommends allowing it if you want to appear. Changes can take up to 24 hours.
Perplexity-User fetches a page when someone asks Perplexity a question and may link to it in the answer. Perplexity says it isn't used for crawling or training, and that because a user requested the fetch, it generally ignores robots.txt rules. The same page has instructions for allowing both bots through a Cloudflare or AWS firewall.
Google: Googlebot and Google-Extended
This is the one most people get wrong. Google's crawler list says Google-Extended has no user agent of its own: Google crawls with its normal crawlers and reads the token as a control. It decides whether content Google crawls may be used to train future Gemini models and for grounding in Gemini Apps and Grounding with Google Search on Vertex AI. Google states that Google-Extended doesn't affect inclusion in Google Search and isn't a ranking signal.
AI Overviews and AI Mode are part of Search. Google's page on AI features says robots.txt rules for Googlebot are the control for Search, and that to limit what is shown from your pages you use nosnippet, data-nosnippet, max-snippet or noindex. It also says there are no extra technical requirements to appear in AI Overviews or AI Mode. Disallowing Google-Extended doesn't take you out of AI Overviews, and blocking Googlebot takes you out of Google Search entirely.
Apple and Common Crawl
Apple says Applebot powers search in Spotlight, Siri and Safari, and its data may also train Apple's foundation models. Disallowing Applebot-Extended opts you out of that training; it doesn't crawl pages, and pages that disallow it can still appear in search results. Common Crawl's page gives the user agent CCBot/2.0 and a two-line rule to block it, and warns that some crawlers falsely identify themselves as CCBot.
The robots.txt gotcha: a named group replaces *
The robots.txt standard (RFC 9309) says a crawler obeys the group that names it, and only falls back to User-agent: * when no group matches. So the moment you add a User-agent: GPTBot group, GPTBot stops reading your * rules. If you need a path private for everyone, repeat that Disallow line in every named group.
A group can list several user agents above one set of rules, which keeps the file short.
Copy-paste file 1: allow search and citation, block training
Replace the sitemap address with yours.
# Training: opt out
User-agent: GPTBot
User-agent: ClaudeBot
User-agent: Google-Extended
User-agent: Applebot-Extended
User-agent: CCBot
Disallow: /

# Search, citation and everything else: allowed
# (OAI-SearchBot, Claude-SearchBot, PerplexityBot, Googlebot, Applebot and the rest use this group)
User-agent: *
Allow: /

Sitemap: https://blog.example.com/sitemap.xml
OAI-SearchBot, Claude-SearchBot, PerplexityBot and Googlebot have no group of their own here, so they follow * and can read everything. The user-triggered fetchers (ChatGPT-User, Claude-User, Perplexity-User) also fall under *.
Copy-paste file 2: allow everything
User-agent: *
Allow: /

Sitemap: https://blog.example.com/sitemap.xml
This lets every crawler that respects robots.txt read every page, for search and for training. If you want to be explicit that AI search bots are welcome, you can add a group for them, but remember the gotcha above: they would then ignore anything you disallow under *.
llms.txt: what it does, and what it doesn't
robots.txt decides who may crawl. llms.txt does something else: it's a Markdown file at /llms.txt that gives AI agents a short summary of your site and links to the pages worth reading, ideally as clean Markdown copies. It doesn't allow or block any bot, so it never replaces robots.txt.
Here is what the official pages say, checked on 11 October 2026:
- The proposal. llms.txt was proposed by Jeremy Howard on 3 September 2024, and the spec at llmstxt.org was revised as v2 on 10 August 2026. It says thousands of sites now publish one, and that OpenAI, Anthropic and Google publish llms.txt files for their own developer docs.
- Google Search. Google's AI features page says you don't need to create new machine-readable files, AI text files or markup to appear in AI Overviews or AI Mode. So llms.txt is not a requirement for Google's AI features.
- Chrome Lighthouse. Lighthouse has an llms.txt audit in its agentic browsing checks. It calls llms.txt an emerging convention, fails the audit only when fetching the file causes a server error, and marks a missing file as not applicable, because providing it is optional for now.
- The crawler pages. OpenAI's, Anthropic's and Perplexity's crawler pages don't say their crawlers read llms.txt. OpenAI's and Perplexity's docs sites do publish one for their own documentation.
My take: llms.txt is cheap to serve and useful to an agent that goes looking for it, such as a coding agent reading docs or an assistant fetching your page for a user. It won't get you into AI search on its own; robots.txt access and readable pages do that.
What blog.lots.blog serves (a worked example)
This is the robots.txt LotsBlog serves on our own blog, https://blog.lots.blog/robots.txt, on 11 October 2026. It is the default every public LotsBlog blog gets:
User-agent: *
Allow: /
Disallow: /api/
Disallow: /_next/
Disallow: /dashboard/
Disallow: /auth/
Disallow: /setup/

# Add sitemap link
Sitemap: https://blog.lots.blog/sitemap.xml
It allows every crawler, AI ones included, to read every article, and keeps them out of app routes that have nothing to read. The other files AI tools look for are served too:
/sitemap.xmllists every published article and topic page with itslastmoddate./llms.txtis a Markdown list of the published articles, each linking to a Markdown copy (/your-post.md), plus links to the RSS feed and sitemap. That follows the llms.txt spec covered above.- Each article page carries
<meta name="robots" content="index, follow">; drafts and preview pages are marked noindex.
To change it, ask your agent. get_blog shows the file your blog serves (robots_txt, with is_custom telling you whether it's your own or the default), and update_blog with robots_txt sets a new one, up to 10,000 characters; sending an empty string restores the default. Or open your blog in the LotsBlog dashboard and go to Settings, General, Robots.txt Configuration, which shows the file currently served; edit it and save. Either way, what you save replaces the default whole, so keep the Disallow lines you want. LotsBlog fills in {{SITE_URL}} with your blog's address, so Sitemap: {{SITE_URL}}/sitemap.xml works on a subdomain or a custom domain, and if your file has no Sitemap line, LotsBlog adds one. The file is cached for up to an hour. If you switch a blog to private, LotsBlog serves Disallow: / and hides the sitemap and llms.txt on its own.
Check that crawlers can actually get in
robots.txt is only half of it. Google's AI features page says to make sure crawling is allowed in robots.txt and by any CDN or hosting infrastructure, and Perplexity's page explains how to allow its bots through a firewall. A firewall or bot-protection setting can turn away a crawler that your robots.txt allows. Three checks:
- Open
https://yourdomain.com/robots.txtin a browser and read what is actually served, on every subdomain. - Check your CDN or firewall settings for AI bot blocking or bot challenges.
- Look for the user agents in your server or CDN logs. OpenAI, Perplexity, Common Crawl and Apple publish IP lists or reverse DNS so you can tell real bots from fakes.
Then give it time: OpenAI says about 24 hours for search, and Perplexity says up to 24 hours.
Where your agent fits
If you run your blog from ChatGPT, Claude or Claude Code, the sitemap, Markdown copies and llms.txt update on their own as your agent publishes, so there is nothing for it to maintain. For how that works, see How to Publish Blog Posts From Claude Code. If you want different crawler rules, your agent can change robots.txt too: ask it to set one of the files above with update_blog and read it back with get_blog. If you're still choosing a platform, The Best Blogging Platforms With MCP Support compares the ones your agent can run. And if you're wondering whether AI-written posts hurt you in Google, I went through Google's own guidance in Does Google Penalize AI-Written Blog Posts?
Give your agent this to set up LotsBlog:
Read https://lots.blog/skill.md and help me connect LotsBlog for you.
LotsBlog costs $9 per blog, or plans from $24 for 3 blogs, with unlimited posts and page views. New accounts get 10,000 free credits, valid 90 days, no card. See pricing.
Common questions
Do I need an llms.txt file?
No. Google says you don't need AI text files to appear in AI Overviews or AI Mode, and Lighthouse treats llms.txt as optional. It's a useful map for AI agents that look for it, and it doesn't replace robots.txt, which is what controls crawler access.
Should I block GPTBot?
Only if you don't want your posts used to train OpenAI's models. OpenAI says GPTBot and OAI-SearchBot are independent, so blocking GPTBot doesn't remove you from ChatGPT search, as long as OAI-SearchBot is allowed.
Does blocking Google-Extended remove my blog from AI Overviews?
No. Google says Google-Extended doesn't affect inclusion in Google Search or ranking. AI Overviews and AI Mode are part of Search and follow Googlebot's rules; to limit what they show, Google points to nosnippet, data-nosnippet, max-snippet and noindex.
What is the difference between ClaudeBot, Claude-SearchBot and Claude-User?
ClaudeBot collects content that may be used for training. Claude-SearchBot indexes content for Claude's search results. Claude-User fetches a page when a Claude user asks about it. Anthropic says all three honor robots.txt.
Can robots.txt stop ChatGPT or Perplexity from opening my page when a user asks?
Not reliably. OpenAI says robots.txt rules may not apply to ChatGPT-User because a user starts it, and Perplexity says Perplexity-User generally ignores robots.txt for the same reason. Anthropic says Claude-User follows robots.txt.
Does my main site's robots.txt cover my blog subdomain?
No. robots.txt applies per host, and Anthropic's page says to add the rule to every subdomain you want to opt out. A blog at blog.yourdomain.com serves its own robots.txt.
How long until a robots.txt change takes effect?
OpenAI says about 24 hours for ChatGPT search, and Perplexity says up to 24 hours. Anthropic says blocking ClaudeBot excludes your future materials from training; it doesn't describe removing content already collected.
Crawler details checked on 11 October 2026 from OpenAI's bots page, Anthropic's crawler help article (dated 7 April 2026), Perplexity's crawler docs, Google's common crawlers list (last updated 14 July 2026), Google's AI features and your website (last updated 10 December 2025), Apple's Applebot page (published 4 September 2026), Common Crawl's CCBot page, RFC 9309, the llms.txt proposal (v2, modified 10 August 2026) and Lighthouse's llms.txt audit (last updated 5 May 2026). Vendors change these pages; check them for the latest.